Best AI for Marketing: 9 Top Models Tested on Real Jobs
I gave nine AI models the same three marketing jobs to find the best AI for marketing writing, and the most consistent winner was not the model I use every day.
Best AI for Marketing in 2026: The Results
Here is the short version from the latest round, run on September 28, 2026. Two blind judges ranked the writing jobs, and a scoring model rated the landing pages.
- Most consistent writer: Grok 4.7. It was the only model both judges ranked in their top three on both writing jobs.
- Blog posts: Grok 4.7, with Claude Opus 5.5, Claude Fable 5.1 and GPT-6 Sol tied right behind it.
- Sales emails: a tie between Opus 5.5 and Grok 4.7. Kimi K3 matched their average rank but broke three rules in the brief.
- Landing pages: no clear winner. Every redesign scored within 0.05 of the others on a zero-to-one scale.
- Weakest: Gemini 3.8 Flash on the blog post, where it recommended two AI models from 2024 as current picks, and DeepSeek V4 Pro on the email.
Claude Opus 5.5 is still my daily driver. That is a workflow choice, not a reading of this data, and I explain it at the end.
The briefs and rules for these tests live in skill files, and I packaged the ones I use daily in my Claude Code Skills Stack.
Most "best AI for marketing" lists compare tools like Jasper, HubSpot and Copy.ai. Many of those tools run on the same few models underneath, so this page tests the models themselves.
Best AI for Marketing Test Rounds and What Changed
This page is a living benchmark. A new round runs whenever a major lab ships a new flagship model, and each round adds to the history below.
- Round 2, September 28, 2026: added Gemini 3.8 Flash, Grok 4.7, DeepSeek V4 Pro and Kimi K3, then re-judged all nine models together. Grok 4.7 became the most consistent writer, and GPT-6 Sol's unchanged Round 1 email fell from first to a 5.5 average, so read every rank as relative to the field.
- Round 1, September 24, 2026: five models (Opus 5.5, Fable 5.1, GPT-6 Sol, GPT-6 Astra and Muse Spark 1.3). Four blog posts tied at an average rank of 2.5, and GPT-6 Sol won the email by a nose.
Round 3 runs on the next major flagship release.
How I Tested the Best AI for Marketing Writing
What makes this ranking different? Every model got the identical brief and was told not to browse, and the judges never saw a model name.
The three jobs are real work from my business. A 500 to 700 word SEO blog post on "best AI models for marketing," a 120 to 180 word sales email for my AI SEO System, and a conversion redesign of that product's real landing page.
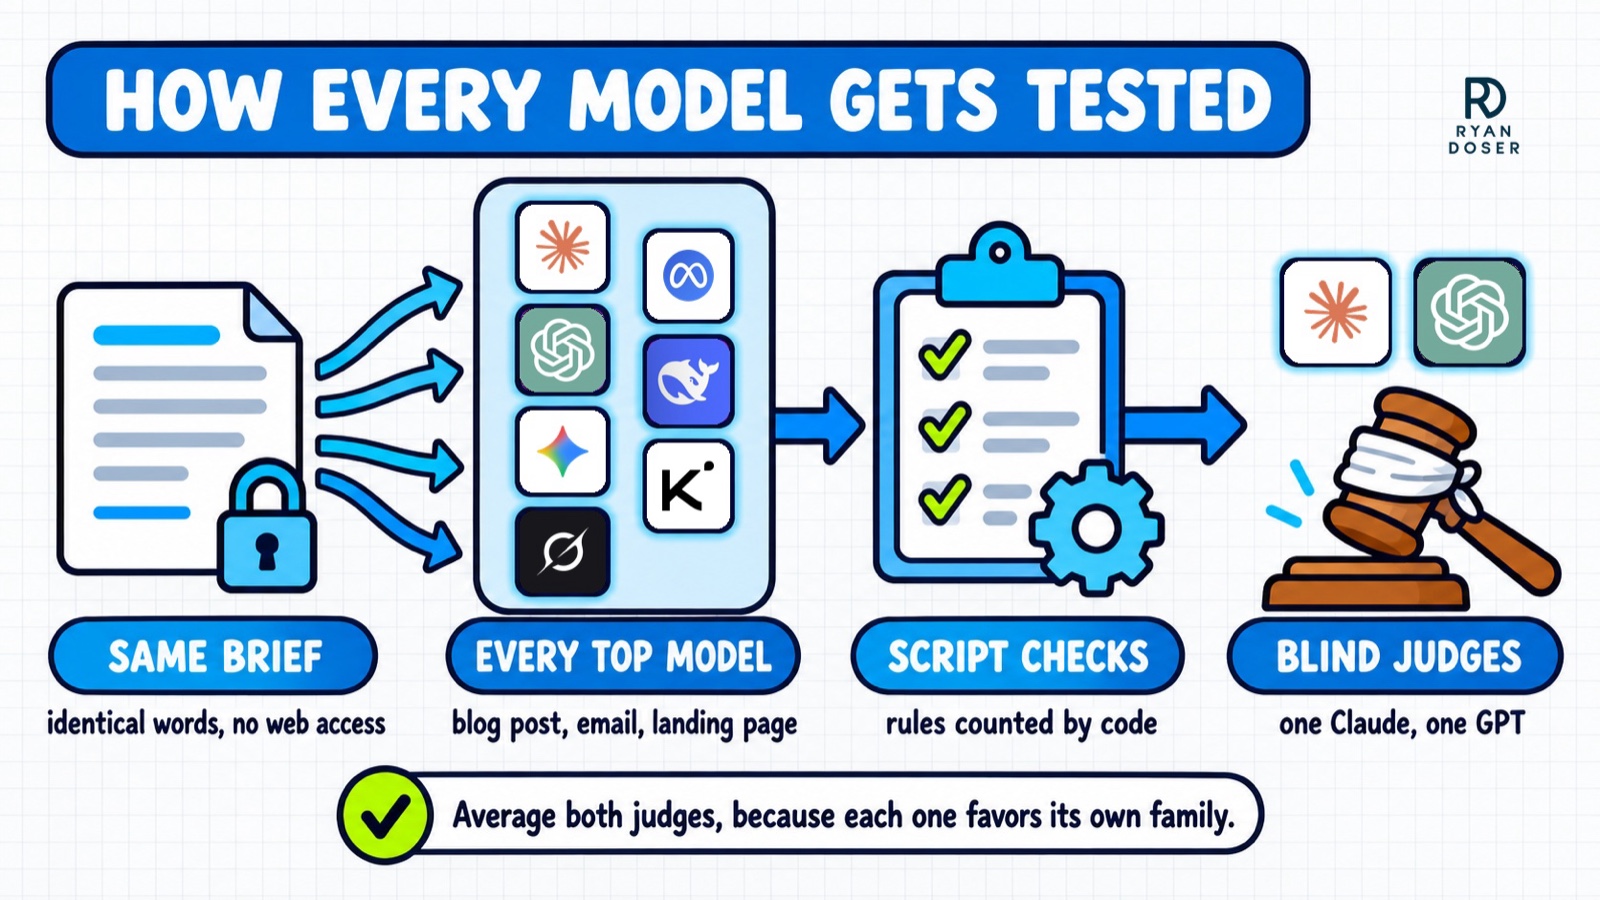
A script checked each output against the brief for length, banned words and em dashes, and checked every number in the emails against the fact sheet. Then two blind judges ranked all nine blog posts and all nine emails, one from the Claude family and one running on GPT-6 Sol.
The nine contestants were Claude Opus 5.5, Claude Fable 5.1, GPT-6 Sol, GPT-6 Astra, Grok 4.7, Gemini 3.8 Flash, Meta Muse Spark 1.3, DeepSeek V4 Pro and Kimi K3. I ran every model outside Claude and OpenAI through OpenRouter, and the four added on September 28 cost $1.24 in total.
One disclosure matters. The four Claude and GPT models ran inside my own workspace, where they could read my general setup notes, while the other five saw only the brief.
That setup could favor the Claude and GPT entries, and Grok still came out as the most consistent writer.
Three of the new jobs also ran out of token budget while the model was still thinking, Gemini's and Kimi's blog posts and DeepSeek's email. I reran each once from the same brief with a higher limit and scored only the finished version.
Gemini 3.8 Flash is in the lineup because Google's newest Pro model is still a preview from February. The first five models ran on September 24 and the last four on September 28, from the same briefs, and all nine were judged together.
Blog Post Test: Grok 4.7 Topped the Average
Grok 4.7 was the only post both judges put in their top three. The Claude judge ranked it third, and the GPT judge ranked it first.
| Model | Claude judge | GPT judge | Average rank |
|---|---|---|---|
| Grok 4.7 | 3 | 1 | 2.0 |
| Claude Opus 5.5 | 2 | 4 | 3.0 |
| Claude Fable 5.1 | 1 | 5 | 3.0 |
| GPT-6 Sol | 4 | 2 | 3.0 |
| GPT-6 Astra | 6 | 3 | 4.5 |
| Kimi K3 | 5 | 6 | 5.5 |
| DeepSeek V4 Pro | 7 | 8 | 7.5 |
| Meta Muse Spark 1.3 | 8 | 7 | 7.5 |
| Gemini 3.8 Flash | 9 | 9 | 9.0 |
That makes Grok 4.7 the best AI for marketing blog posts in this round. Opus 5.5, Fable 5.1 and GPT-6 Sol tied at 3.0 behind its 2.0 average.
Grok wrote in short, confident lines and added guardrails a real marketer would use. One example: "Keep that pick for a month." The GPT judge called it "specific, memorable advice with strong editorial judgment."
Its weak spot was a made-up personal detail, a claim that "most of my clips are 6 to 15 seconds." Meta Muse Spark 1.3 went further and invented a weekly team routine I do not have, which is why I never publish a draft without reading it.
Fable 5.1 earned the top copy score from both judges, tied with Grok on the GPT side. That judge still ranked it fifth overall, saying its SEO advice "makes automation sound more automatic than it is."
Three Models Recommended AI That Is Already Outdated
Told not to browse, a model asked for the best AI for marketing can only answer from its training data. Three of the nine recommended outdated versions, even though the brief told them to name the model family whenever they were unsure a version was current.
- Gemini 3.8 Flash picked "Claude 3.5 Sonnet" for copywriting and "GPT-4o" for data work. Both launched in 2024 and have been replaced several times since.
- Kimi K3 called GPT-4o "a close second" for writing.
- DeepSeek V4 Pro suggested DALL-E 3 for images inside ChatGPT, which now uses OpenAI's newer image model.
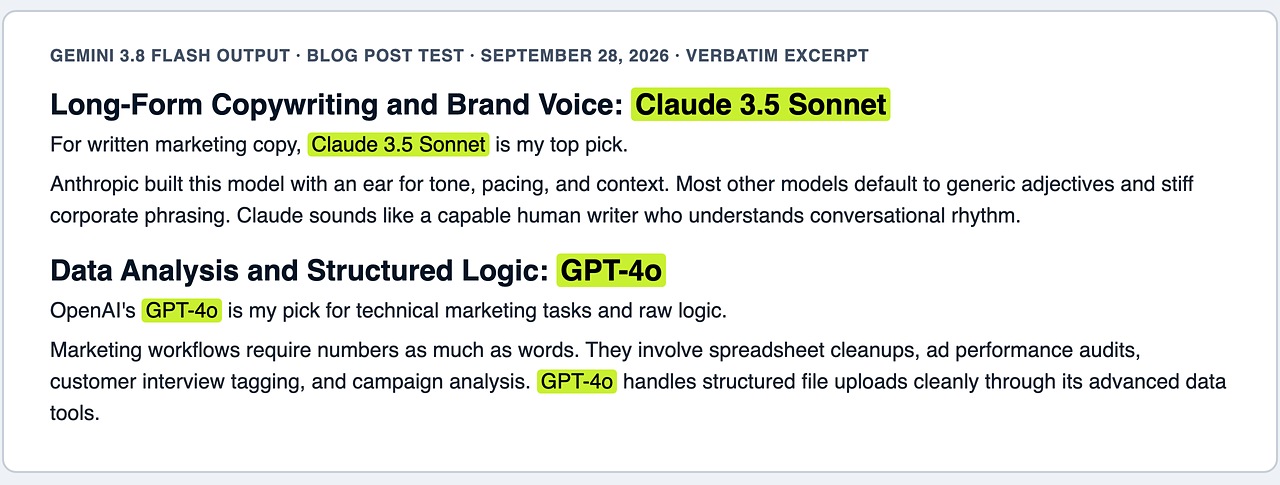
Gemini also claimed that "standard chat models struggle with search because they pull facts from static training data." ChatGPT, Claude and Gemini all search the web today, and both judges gave Gemini their lowest accuracy score of the round.
The takeaway works for any AI tool. When a model recommends a product without searching first, check the release date before you pay for it.
My breakdown of which writing tools are just wrappers covers the markup side of that decision.
Sales Email Test: A Tie at the Top
Email is the job closest to revenue, and best AI for marketing lists rarely test it head to head. This test measured judge preference, not real sales.
Each model got a fact sheet for my $199 AI SEO System and one rule above the rest: use only those facts.
| Model | Subject line | Claude judge | GPT judge | Average | Rule breaks |
|---|---|---|---|---|---|
| Claude Opus 5.5 | Is AI search naming you or a competitor? | 3 | 2 | 2.5 | None |
| Grok 4.7 | How I got 12.1K AI citations | 2 | 3 | 2.5 | None |
| Kimi K3 | how I got 12,100 AI citations in 6 months | 1 | 4 | 2.5 | Three |
| GPT-6 Astra | Who does AI recommend instead of you? | 7 | 1 | 4.0 | One |
| Claude Fable 5.1 | Is AI search skipping your website? | 4 | 6 | 5.0 | None |
| GPT-6 Sol | Does AI search name you or a competitor? | 6 | 5 | 5.5 | None |
| Gemini 3.8 Flash | How to show up in AI search | 5 | 8 | 6.5 | None |
| Meta Muse Spark 1.3 | AI search is changing who gets found | 8 | 7 | 7.5 | None |
| DeepSeek V4 Pro | Your site is invisible to AI search | 9 | 9 | 9.0 | None |
Kimi K3 was the Claude judge's favorite email, but it broke three rules. It ran over the word limit, never used the phrase "AI search" the brief asked it to lead with, and rewrote my "12.1K" citations as "12,100," a precision the fact sheet never claimed.
That leaves Opus 5.5 and Grok 4.7 as the clean winners, and I call it a true tie. Each judge ranked one of them above an email from its own family, so neither cross-family read breaks it.
DeepSeek V4 Pro came last with both judges. "Your site is invisible" is exactly the fear-based hype my list tunes out.
Landing Page Test: No Clear Winner
Landing pages were the one job where no model looked like the best AI for marketing. None clearly beat my own page.
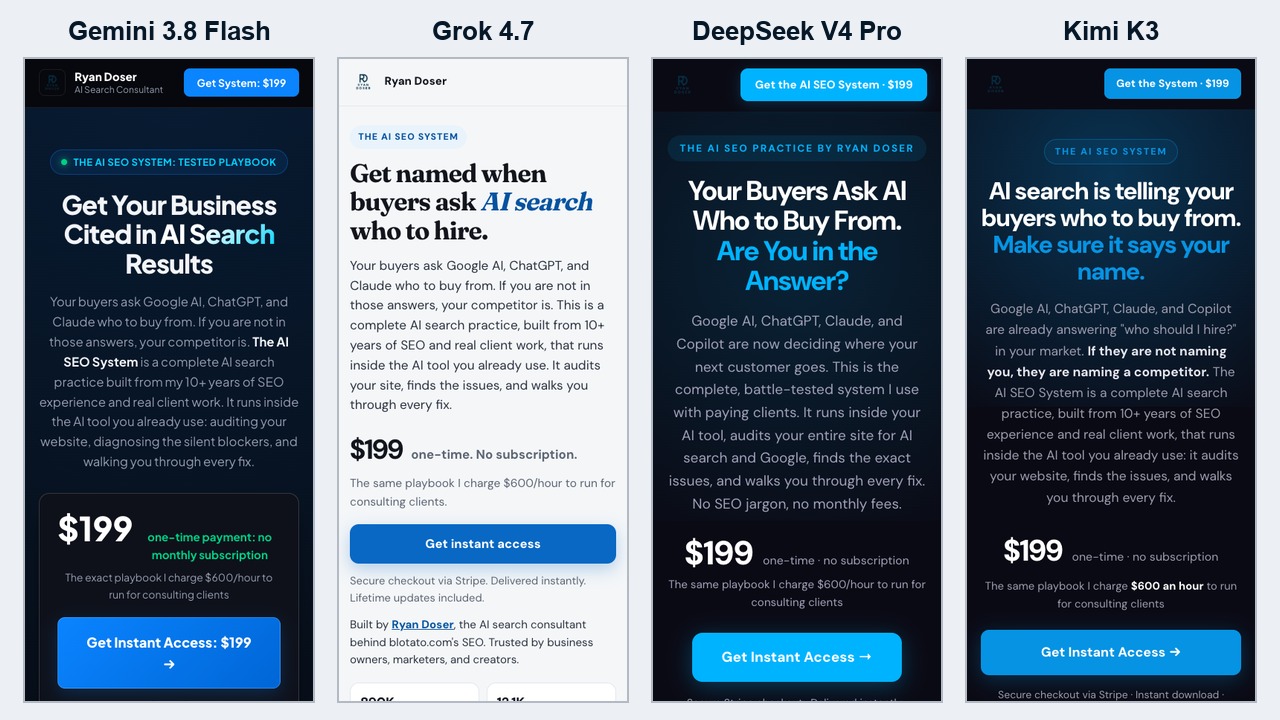
Every page, including my live original, scored between 0.53 and 0.58 on "would a skeptical owner buy" from Jev, a scoring model on OpenRouter. That spread is too small to pick a winner, and no page was tested on real visitors.
Three of the new pages also skipped a required part of the brief, a comment explaining their conversion choices. Landing pages stay my call, and I review them by eye before anything ships.
Each Judge Favored Its Own Family, Mostly
For the blog posts, the Claude judge ranked the two Claude posts first and second, and the GPT judge put the two GPT posts second and third. The bias is not absolute, since the Claude judge put Kimi K3's email first and no Claude email in its top two.
If a best AI for marketing ranking uses a single AI judge, it may be measuring that judge's taste as much as the writing. I dig into why blind judges still pick their own family in my Opus 5.5 vs GPT-6 breakdown.
It is also why every draft I publish gets a second read from a model outside the family that wrote it, a setup I explain in how I run Claude Code and Codex together.
What I Still Use, and When This Test Runs Again
Claude Opus 5.5 stays my daily driver, for workflow reasons more than test results. It tied for the email win, it placed second with the Claude judge on the blog post, and my whole workflow already runs on it, as I covered in why I switched to Opus 5.5 for writing.
Grok 4.7 is the model to watch in the next round. One run per model per job is a snapshot, not a verdict, so this best AI for marketing page gets a new round whenever a major model ships.
Google says Gemini 4 is coming "as soon as possible," and it goes into Round 3 once it ships.
Best AI for Marketing FAQs
What is the best AI for marketing right now?
For marketing writing, Grok 4.7 was the most consistent model in my September 28, 2026 test, finishing in both blind judges' top three on the blog post and the sales email. Claude Opus 5.5 tied Grok for the email win, and no model clearly won the landing page test. Treat any ranking like this as a dated snapshot.
Is Claude or ChatGPT better for marketing?
It depends on who is judging. Claude Opus 5.5 and Fable 5.1 tied GPT-6 Sol at 3.0 for blog writing in my test, and Opus beat both GPT models on average rank for the sales email. A Claude judge favored the Claude posts and a GPT judge favored the GPT posts, so compare both judges before you trust any single winner.
What AI is better than ChatGPT for writing?
In my blind test, Grok 4.7 outranked both GPT-6 Sol and GPT-6 Astra on the blog post, and Claude Opus 5.5 and Grok 4.7 both outranked them on the sales email. GPT-6 Astra still got the GPT judge's first place for its email, so ChatGPT's models are close, not far behind.
Is Gemini good for marketing writing?
Google's Gemini 3.8 Flash was not, in this round. It finished last in the blog writing test with both judges, and the GPT judge flagged its dated picks of Claude 3.5 Sonnet and GPT-4o plus its missing video and SEO advice. Google's newest Pro model is still a February preview, so its standing could change quickly once Gemini 4 arrives.